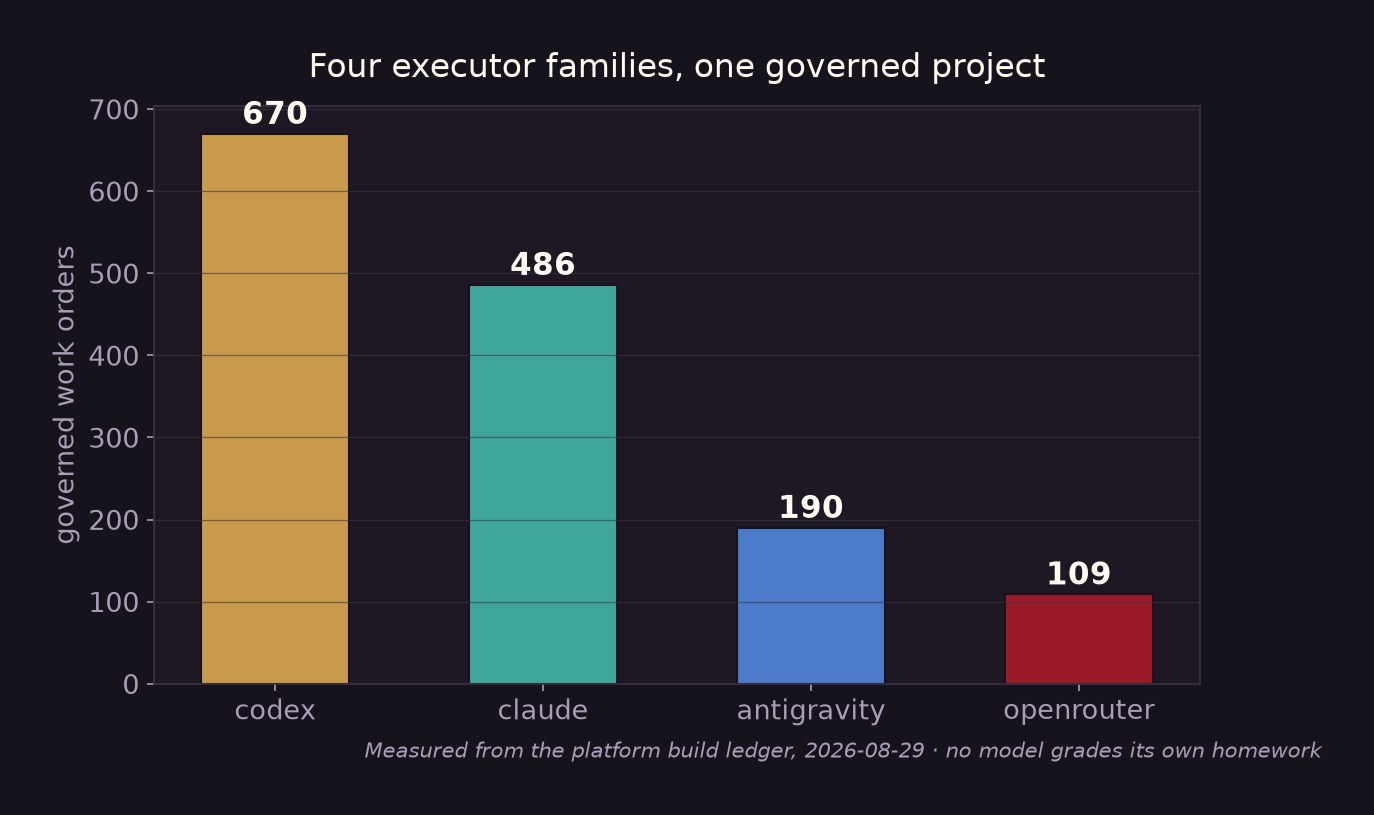
Proof: which workers did the best work, and what it cost
Every model that has taken a seat in Auteur's own construction, ranked from the receipts. This is the dataset behind the governed build-campaign demonstration on the home page, and it is the same ledger the studio reads when it picks a seat for the next round.
Two words carry the whole table. Finished means an attempt ended done and passed the tests its task declared; nothing else counts. Tries counts every attempt, including the ones verification stopped. A caught failure is the product working, so the low rows stay on the page.
Paid seats are metered in dollars by their provider, to the cent. Subscription seats are the flat-rate plans you already carry, so there is no dollar to show for a task and we do not invent one: they are measured in tasks, minutes and new tokens instead.
Receipts, not vibes · measured 2026-09-02
Paid seats, metered in dollars
| Worker | Tries | Finished | Pass rate | Metered spend | Spend reported | Cost per finished task |
|---|---|---|---|---|---|---|
| Qwen3.8 Maxqwen/qwen3.8-max · high effort | 26 | 20 | 77% | $13.82 | 24 / 26 | not enough data |
| GLM 5.2z-ai/glm-5.2 · high effort | 64 | 21 | 33% | $14.11 | 36 / 64 | not enough data |
| Kimi K3moonshotai/kimi-k3 · high effort | 5 | 1 | 20% few tries | $4.92 | 4 / 5 | not enough data |
| Grok 4.6x-ai/grok-4.6 · high effort | 7 | 1 | 14% few tries | $4.60 | 6 / 7 | not enough data |
| Gemini 3.5 Flashgoogle/gemini-3.5-flash · high effort | 7 | 0 | 0% few tries | – | 0 / 7 | no price reported |
Why "not enough data" on a paid row: a cost per finished task is only shown when every try reported its spend. A silent try makes the ratio a guess, and guesses are not published as measurements. Why the low pass rates are on the page: a caught failure is the product working. Those tries were stopped by verification before anything shipped.
Subscription seats, measured in tasks, minutes and tokens
| Worker | Tries | Finished | Pass rate | Minutes per finished task | New tokens per job | Dollars |
|---|---|---|---|---|---|---|
| Claude Opus 4.8claude-opus-4-8 · high effort | 21 | 21 | 100% | 9.0 | 470k | flat-rate |
| Claude Sonnet 5claude-sonnet-5 · high effort | 142 | 126 | 89% | 11.4 | 430k | flat-rate |
| Claude Sonnet 5claude-sonnet-5 · xhigh effort | 62 | 54 | 87% | 16.2 | 571k | flat-rate |
| Claude Opus 5claude-opus-5 · xhigh effort | 136 | 116 | 85% | 27.4 | 562k | flat-rate |
| Codex, GPT-5.6 Solgpt-5.6-sol · max effort | 23 | 19 | 83% | 23.2 | 179k | flat-rate |
| Claude Opus 5claude-opus-5 · high effort | 119 | 97 | 82% | 20.6 | 411k | flat-rate |
| Gemini 3.7 Flash, via Antigravitygemini-3.7-flash · high effort | 30 | 24 | 80% | 12.5 | 311k | flat-rate |
| Codex, GPT-5.6 Solgpt-5.6-sol · medium effort | 15 | 12 | 80% few tries | 7.0 | 91k | flat-rate |
| Codex, GPT-5.6 Solgpt-5.6-sol · high effort | 336 | 259 | 77% | 14.8 | 133k | flat-rate |
| Claude Haiku 4.5claude-haiku-4-5 · high effort | 4 | 3 | 75% few tries | 7.2 | 258k | flat-rate |
| Codex, GPT-5.6 Lunagpt-5.6-luna · high effort | 94 | 70 | 74% | 10.4 | 134k | flat-rate |
| Codex, GPT-5.6 Solgpt-5.6-sol · xhigh effort | 234 | 165 | 71% | 22.1 | 203k | flat-rate |
| Earlier or unlisted seatsmodel version not recorded | 96 | 68 | 71% | 16.4 | 341k | flat-rate |
| Codex, GPT-5.6 Terragpt-5.6-terra · medium effort | 7 | 5 | 71% few tries | 10.9 | 76k | flat-rate |
| Gemini 3.6 Flash, via Antigravitygemini-3.6-flash · high effort | 91 | 64 | 70% | 6.9 | – | flat-rate |
| Claude Haiku 4.5claude-haiku-4-5 · medium effort | 6 | 4 | 67% few tries | 11.3 | 266k | flat-rate |
| Gemini 3.7 Flash, via Antigravitygemini-3.7-flash · medium effort | 9 | 5 | 56% few tries | 17.0 | – | flat-rate |
| Gemini 3.1 Pro, via Antigravitygemini-3.1-pro · high effort | 55 | 27 | 49% | 16.9 | 522k | flat-rate |
| Claude Opus 5claude-opus-5 · max effort | 30 | 13 | 43% | 61.5 | 274k | flat-rate |
| Codex, GPT-5.6 Lunagpt-5.6-luna · xhigh effort | 2 | 0 | 0% few tries | – | 141k | flat-rate |
"New tokens" is what the model read or wrote for the first time. Cache re-reads are the provider's discount, not our work, so they are not counted. Rows under 20 tries are dimmed: a perfect score from a handful of attempts is a hint, not a fact.
Pass rate by worker, with how many tries it rests on
Bar length is the share of tries that finished and passed their tests. The number after each bar is the try count; only workers with 20 or more tries are charted. Shorter bars are not hidden: they are the proof that verification catches what a model gets wrong.
Read from the operator dashboard on 2026-09-02. Live counters; they keep moving as builds complete.
How to read this honestly
More effort is not more finish. The same model at its highest reasoning setting finished fewer of its tries and took three times as long as it did at a high setting, and the same pattern holds across providers. Auteur's seat selection is drawn from rows like these, not from a leaderboard someone else ran on a benchmark that is not your work.
A cost per finished task is only shown when every try reported its spend. A partial sum divided by a full count would understate the true cost, so the column reads "not enough data" until the coverage is complete.
Cache re-reads are not counted as work anywhere on this page. When a provider serves a token from cache it is that provider's discount, on every tool that uses the same model, so it belongs to them and not to us.